LLM fine-tuning and evaluation
Quantlix adapts language models to task-specific examples and evaluates whether fine-tuning improves behavior, consistency and practical task performance.
A clear purpose. A practical approach.
Fine-tuning changes model behavior through examples. Quantlix first defines the behavior that matters and a baseline to compare against.
A dataset can reinforce errors or expose sensitive material. Start with reviewed examples and test difficult cases before choosing a production release.
Where we can help
A focused scope, shaped around your priorities.
Dataset preparation
Review example quality, permissions, labels and sensitive information.
Targeted adaptation
Train for a defined task, style or output format.
Comparative evaluation
Compare the adapted model with prompts and existing baselines.
A measurable adaptation loop
Separate training examples from evaluation tasks to assess useful generalization.
- Reviewed examples
- Adapted model
- Held-out evaluation
- Release decision
What the work puts in your hands
Agree on useful, reviewable deliverables before the work begins.
- Dataset specification
- Adapted model artifacts
- Evaluation report
- Deployment recommendation
Good work starts with a shared understanding.
We make the decisions together, then make the next step clear.
Start with the real problem
Discuss the people, business goals and constraints behind the request. Agree on the scope and what a useful outcome looks like.
Make the direction tangible
Use working sessions, research and early drafts to explore the options. Review the tradeoffs with your team before committing to a direction.
Work in reviewable increments
Bring the agreed work into focus through regular reviews. Document the decisions, hand over the deliverables and plan any ongoing support.
Questions, answered
The practical details to consider before starting.
When should we fine-tune?
Consider fine-tuning for repeated task behavior after testing simpler prompting and retrieval approaches.
Does fine-tuning keep facts current?
Frequently changing facts usually need retrieval or system integration alongside the model.
What data is required?
Use representative, permissioned examples with consistent expected outputs and a separate evaluation set.
Quantlix develops AI systems for prediction, language understanding and image analysis, with evaluation, human oversight and integration into business workflows.
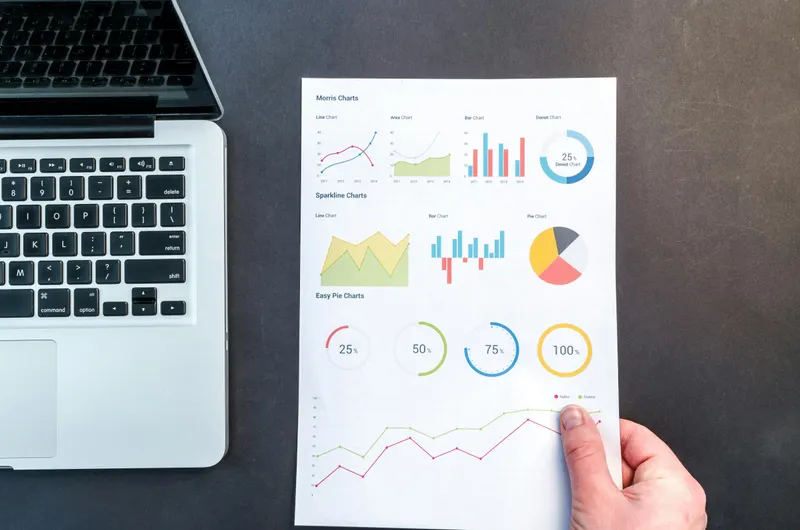
Quantlix builds analytics pipelines and business intelligence tools that turn operational data into defined metrics, useful reports and decision support.
Quantlix builds generative AI workflows for drafting content and creating assets, with brand guidance, review controls and integration into publishing processes.
Let’s talk about what needs to change.
Bring your challenge, your questions and your starting point. We’ll work out the next step together.